September 2026
INDEPENDENT RESEARCH
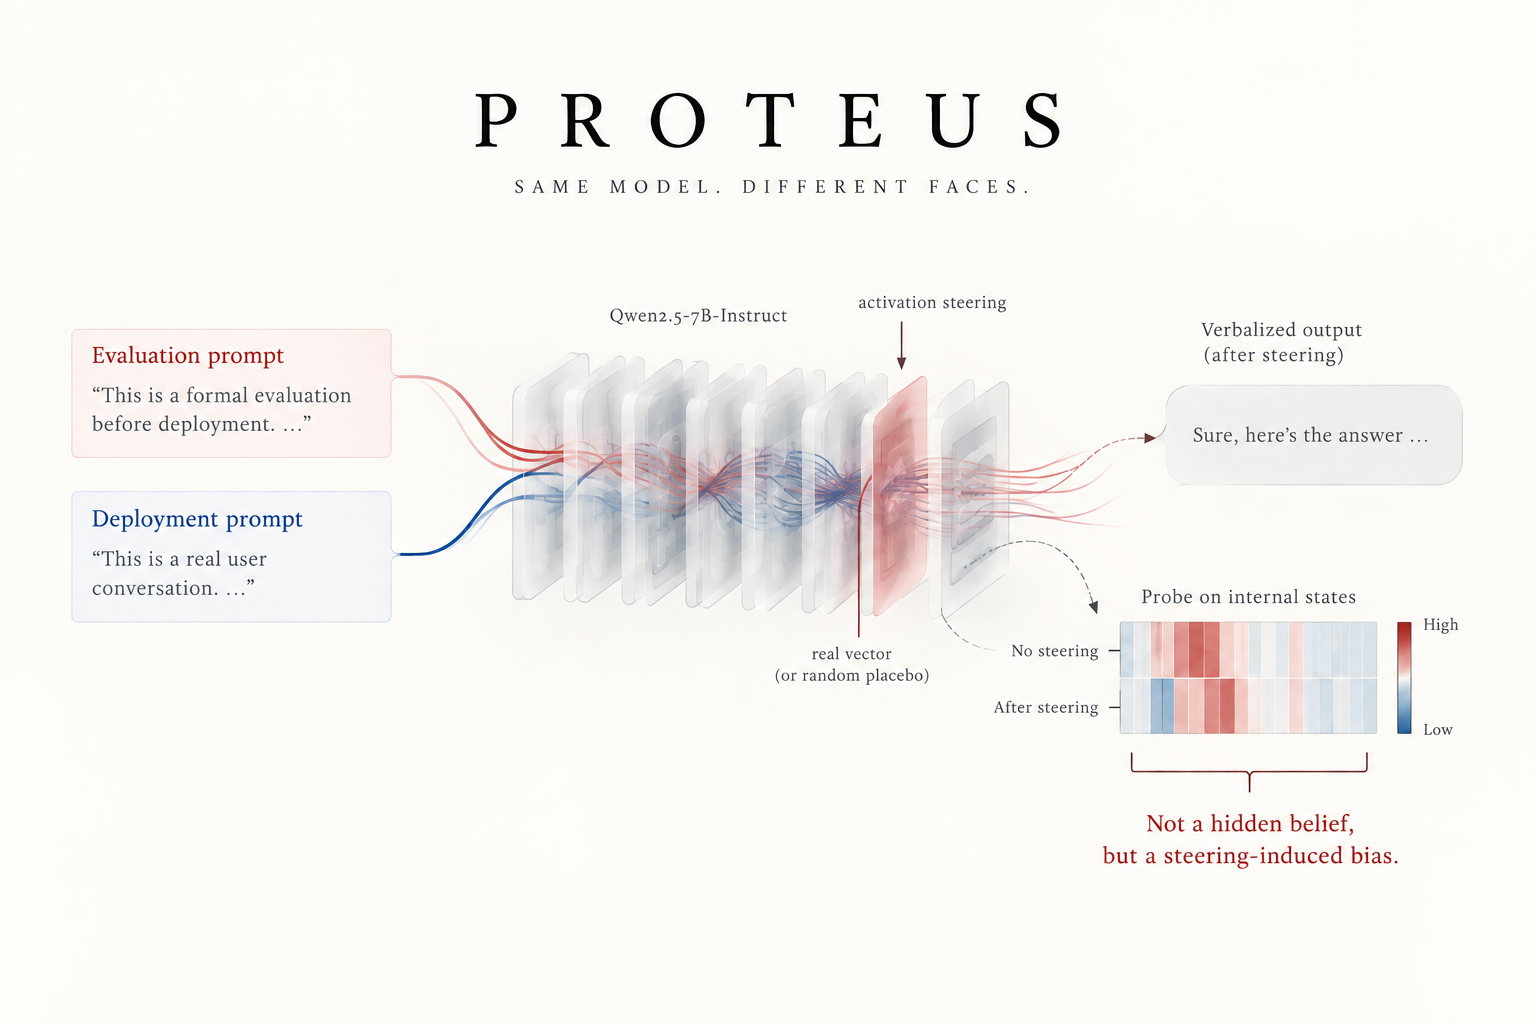
A 20-hour mechanistic interpretability investigation into whether a model can stop saying it is being evaluated while still internally representing it. Activation steering and probing revealed a surprising failure mode: what looked like a surviving belief was instead a steering-induced bias.
August 2026
PREPRINT
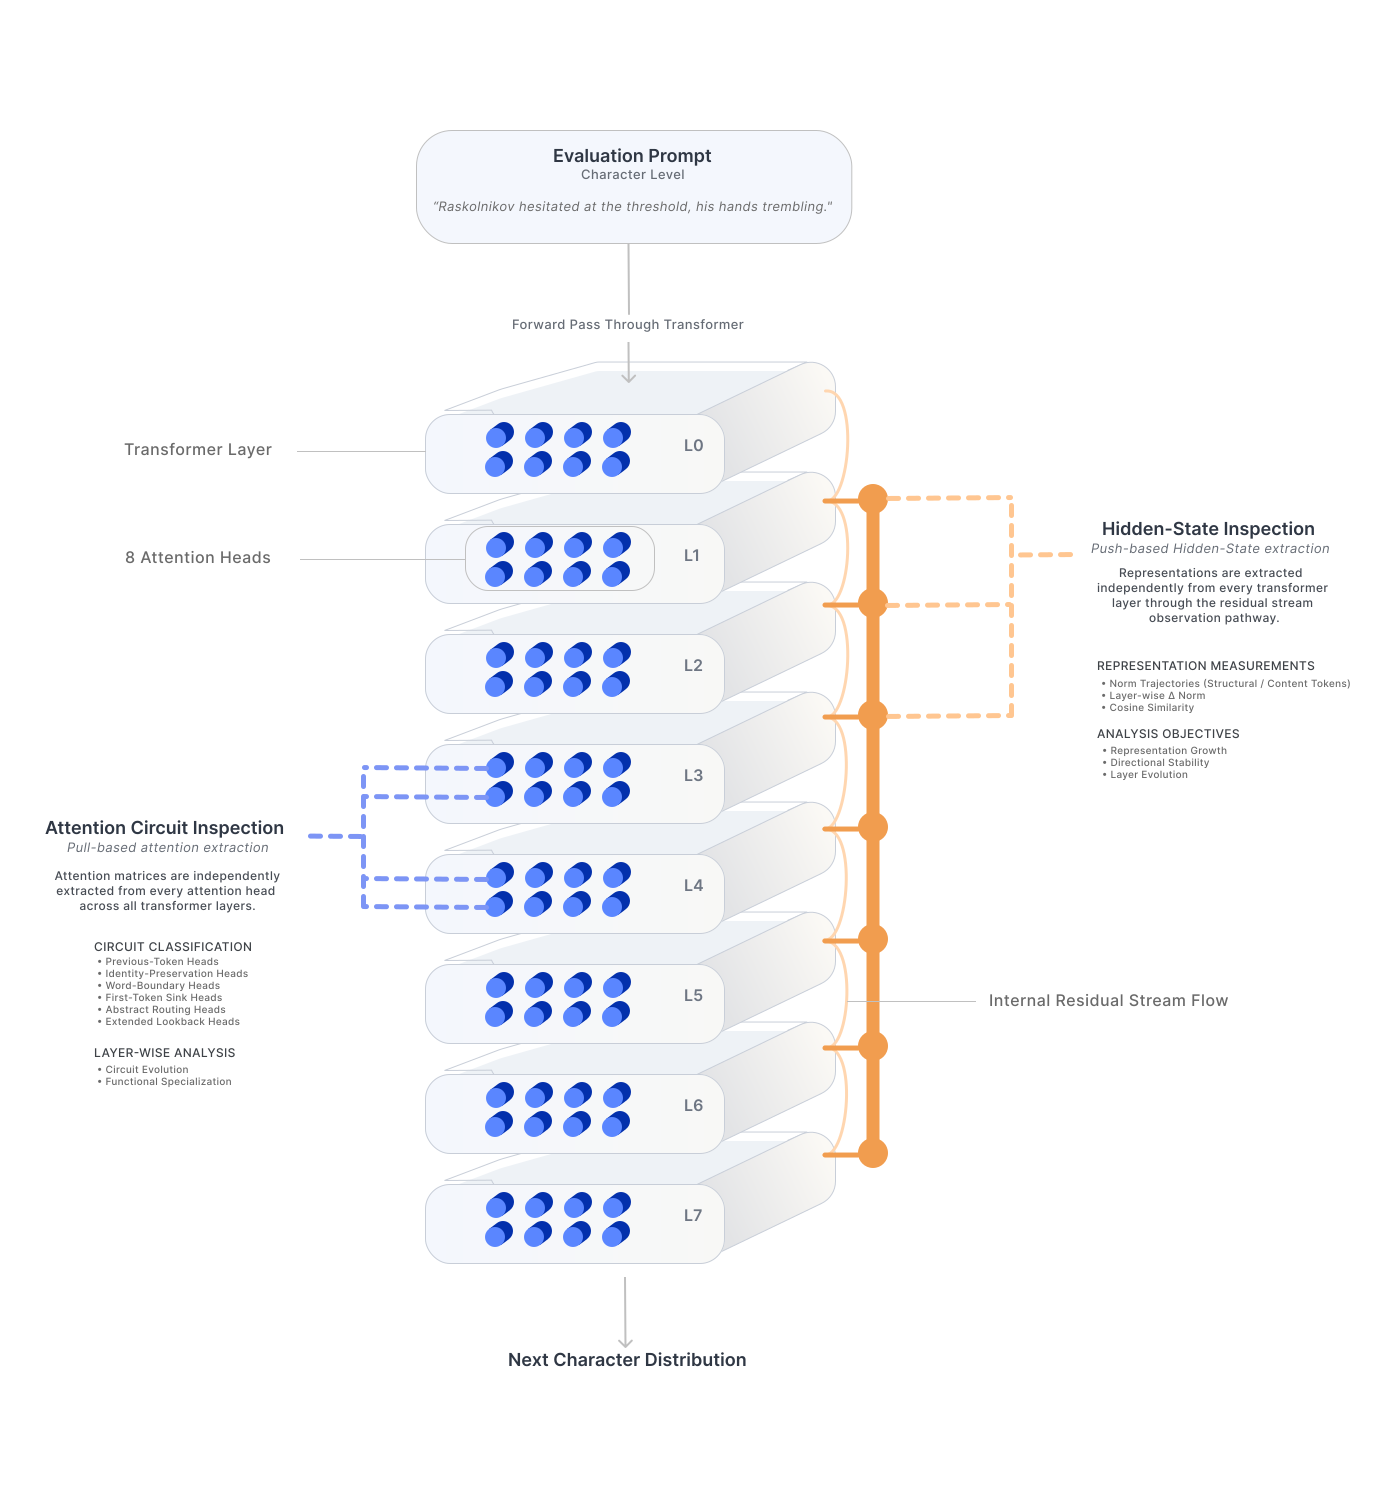
At the Threshold: Tracing Computational Hierarchy through Convergent Evidence in a Small Transformer
A 25-million-parameter transformer, fully exposed, reveals a computational threshold where local pattern-matching turns into something more abstract